
Keep the call visible
Anchor the assessment to the conversation instead of separating review from evidence.
Delivered case study · Conversation assessments
Exploring how customer-centre supervisors could move from manually reviewing a small sample of calls to finding the conversations that need attention.
Reviewing customer conversations is part of the supervisor and customer-centre manager role. They check whether customer experience professionals follow the expected script, meet regulatory and internal requirements, and receive support or training when needed.
The workflow supports structured assessments, but every review still requires someone to open the call, listen manually or check the transcription and record the outcome.
Because conversations were assessed one at a time, supervisors could review less than 5% of calls in an average week. This limited their view of the wider operation and made issues difficult to track and address through ongoing monitoring.
I worked with the same core team as the wider customer-centre experience, focusing this phase on discovery, framing and structural foundations.
Scope note: later development expanded to external integrations and moved to another team.
Anchor the assessment to the conversation instead of separating review from evidence.
Use consistent language operators and question structures across products.
Help reviewers connect each judgement to a specific moment in the conversation.
Support live coaching, historical review and a model that can grow.
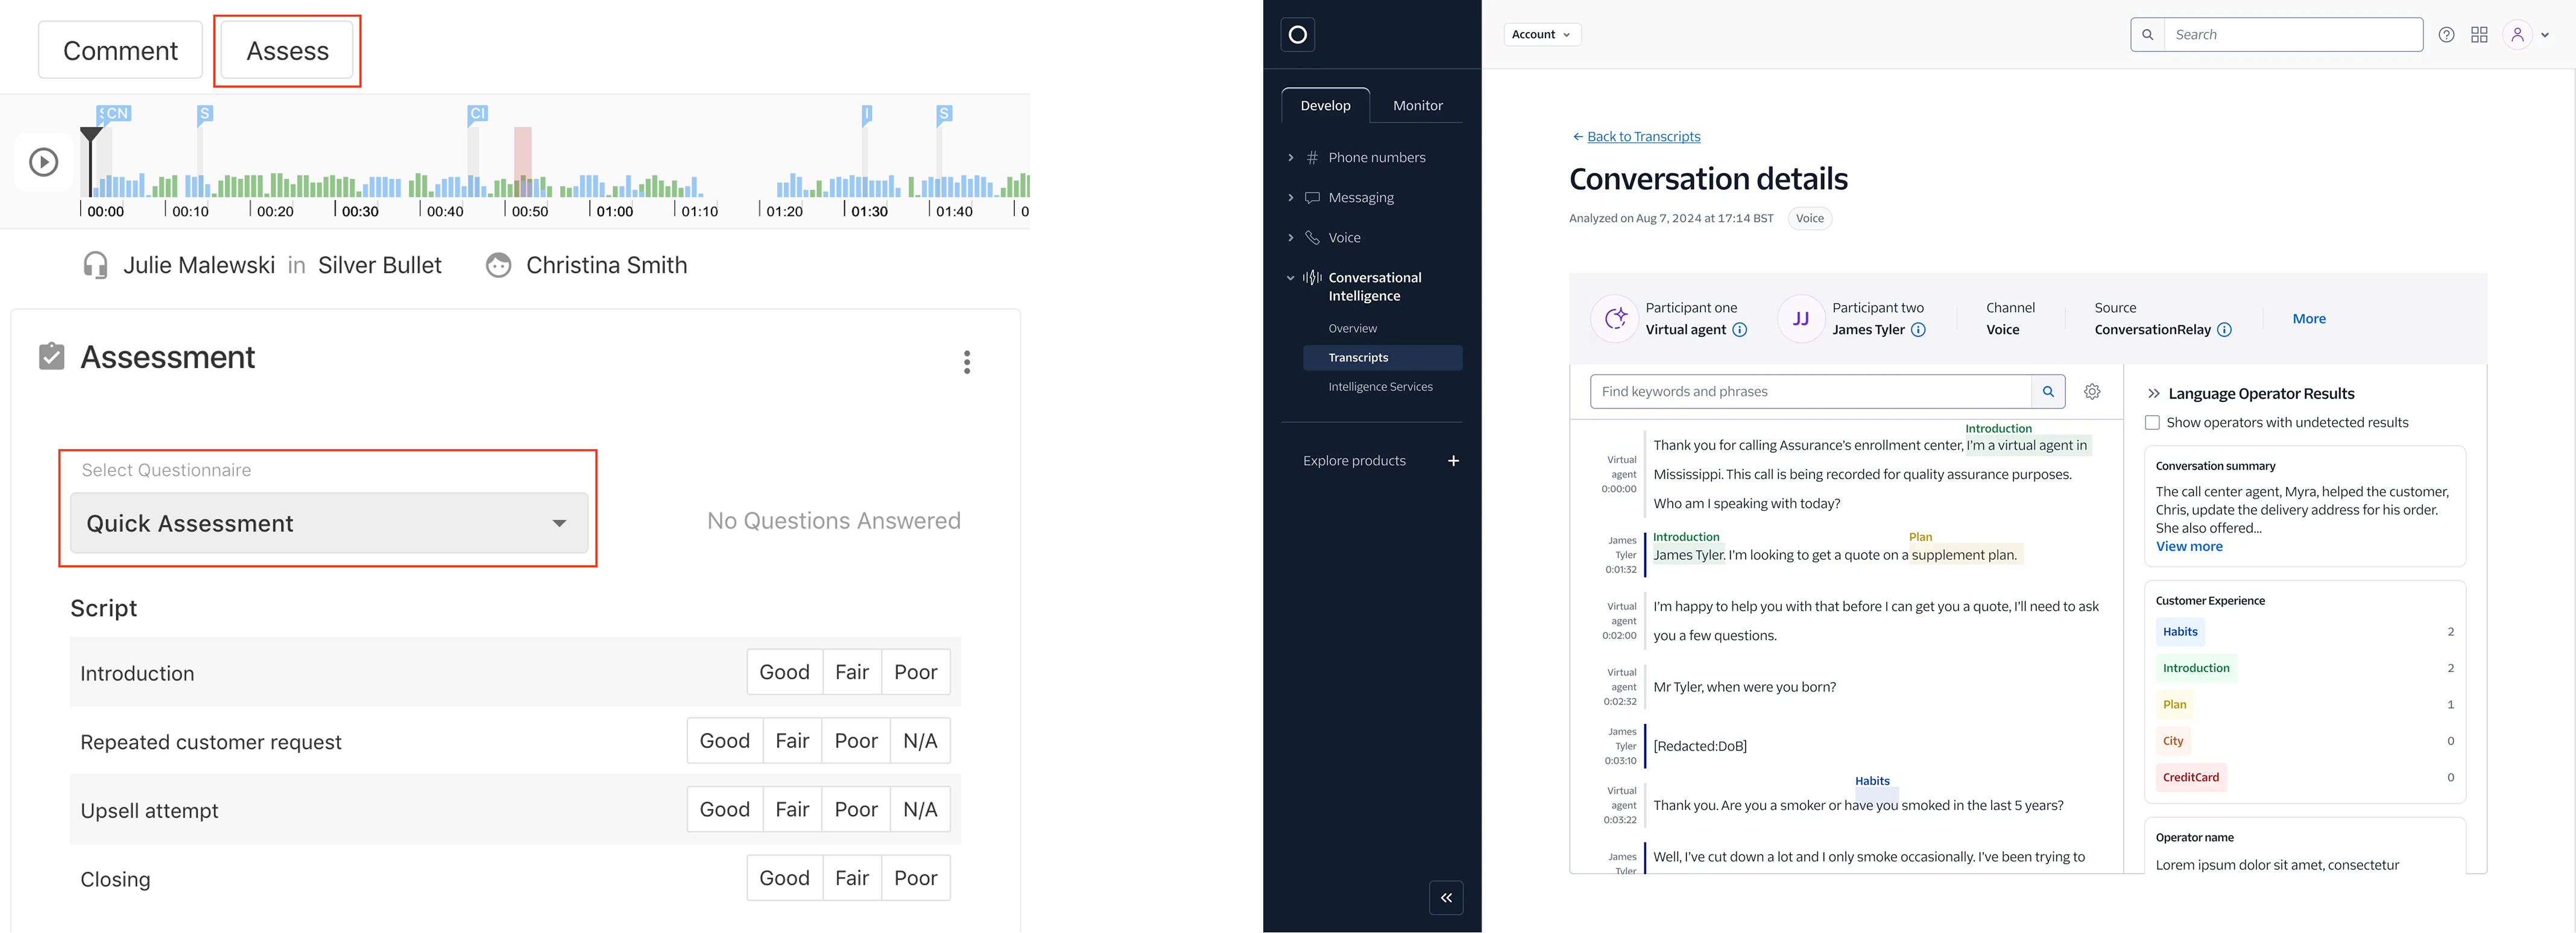
A supervisor searched historical reporting for one conversation, opened the call, selected a questionnaire and rated each question. Comments could be added before the assessment was saved.
The screen kept the call context and assessment task together. Select a view to explore how the structure supported the review.
The timeline, conversation context and questionnaire stay together so the supervisor can assess the call without losing orientation.
The same assessment structure can support historical review, live coaching and product-specific integrations. Coverage can move from less than 5% of calls reviewed manually to up to 100%* through connected criteria and automation.
*Coverage is configurable by an administrator or developer, depending on the product setup. Research indicated that admins may set specific queues to 100% coverage and others to 0%, based on contract scope, legal requirements and cost.
Voice, chat and digital channels can use the same review structure.
Supervisors, managers and quality teams share a consistent pattern.
External providers can supply signals without changing the assessment frame.
Open one call → listen → tag manually → rate each question.
Keep context visible → apply connected criteria → record structured evidence → coach with context.
Caller, queue and timeline anchor the supervisor in the selected conversation.
The questionnaire selector sets the script or criteria being applied.
Shared rating controls support quick review, with comments available when context is needed.
Open one call → listen → tag manually → rate each question.
Keep context visible → apply a questionnaire → record structured evidence → coach with context.
Previously, questionnaires were uploaded manually, one by one or in batches. The new direction supports prompting or API-based access to existing questionnaires, depending on the product.
Prompt for a language operator or connect an existing one through an API, depending on the product.
Select reusable language operators to build the criteria for this assessment.
Select items for display.
To prevent scrolling, select up to 6 items
Analysed on Aug 7, 2024 at 17:14 BST Voice
Assistant
00:00:00IntroductionThank you for calling the enrolment centre. I’m a virtual assistant. How can I help today?
Alex Morgan
00:01:32IntroductionI’m looking for help with my account.
Assistant
00:02:00I’m happy to help with that. I’ll ask a few questions first.
Alex Morgan
00:03:10PlanI’d like to understand the available options.
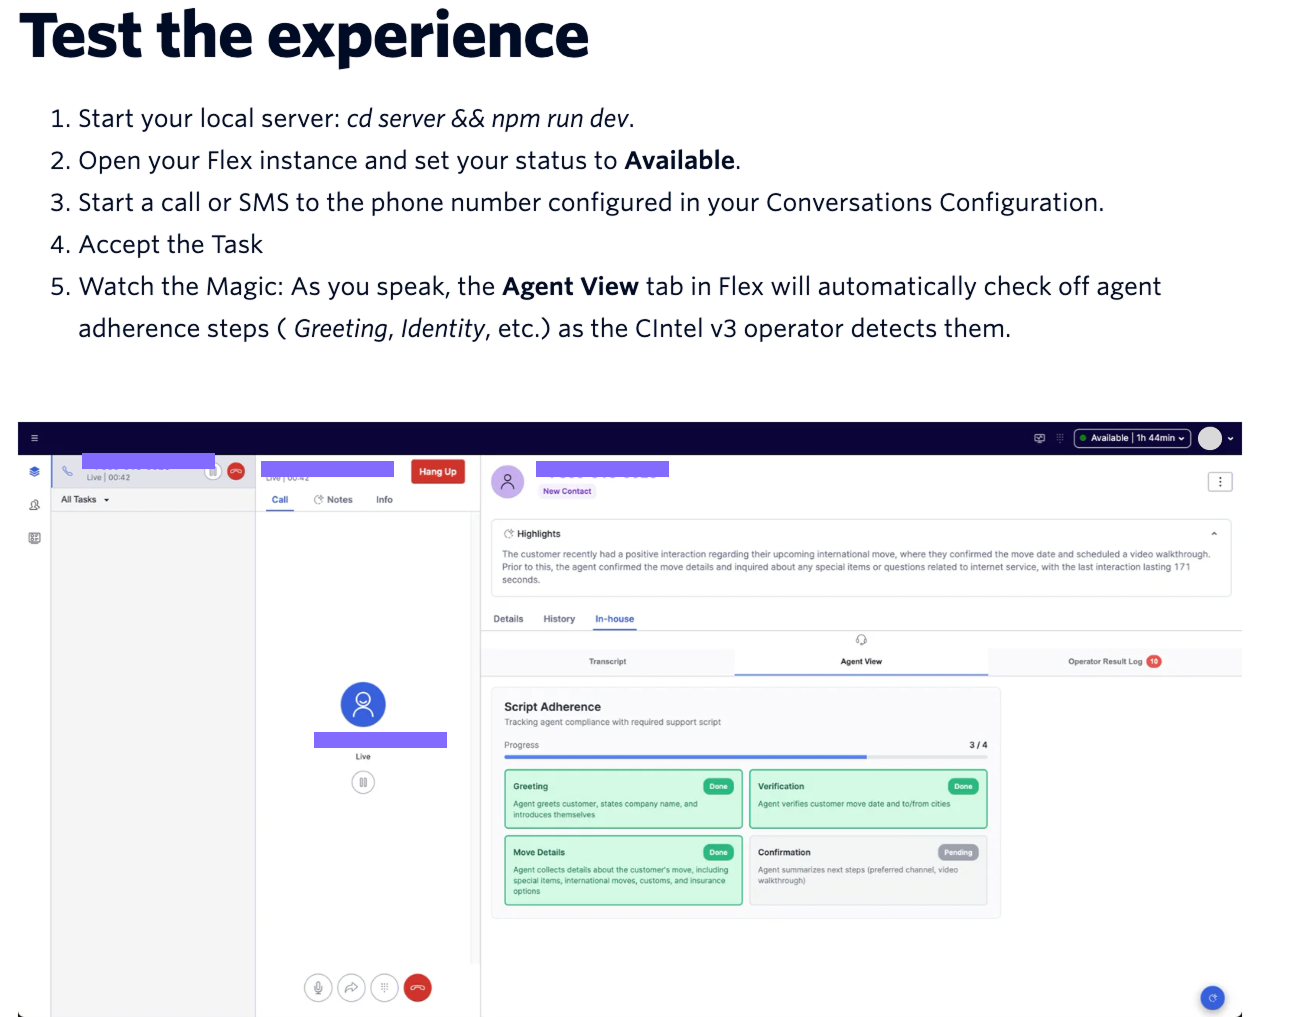
Supervisors can observe an active conversation while a customer experience professional is working, or return to historical reporting for a completed assessment. The same signals and user context carry across both views.
Voice, chat and digital channels can use the same review structure.
Supervisors, managers and quality teams share a consistent pattern.
External providers can supply signals without changing the assessment frame.
 +44 20 7946 0958Alex MorganChristina Smith
I used lightweight concepts and working prototypes to explore how questionnaire setup, question reuse and conversation evidence could fit together. Each iteration focused on a decision the team needed to make before moving into development.
Tested how the conversation, questionnaire and assessment actions could share one focused surface.
What to test → orientation while reviewingExplored a prompt or API-led path for adding language operators and assembling product-specific questionnaires.
What to test → setup effort and flexibilityRendered operator results next to the transcript so a supervisor could connect a signal with the conversation context.
What to test → confidence in the evidenceValidated the prototype against the existing questionnaire model. Titles could change without losing assessment history, but changing a question’s meaning could make reports difficult to interpret. Teams could duplicate a question, then rename and edit the copy without changing other questionnaires or historical analysis.
What to test → safe evolution without changing historical reportsHow might we help supervisors understand which conversations need attention, identify patterns across a larger sample, and focus human review where it has the greatest impact?
Open one call → choose a questionnaire → listen → rate every question → add comments.
Surface meaningful signals → prioritise review outliers → understand patterns → identify root causes and coach with context.
This first version establishes the current workflow and the scale problem. The next iteration will add the design direction, research evidence, collaboration model and outcome once those details are confirmed.
The opportunity is to move from a small, manually selected sample towards structured signals that help teams see patterns, focus review and coach with context.
Surface meaningful signals→Prioritise review outliers→Understand patterns→Coach with context